01
ZhangYvJing's
Daily Brief
00
Film / Book Chapter
Paterson
Paterson (2016) · Jim Jarmusch
今天适合看《Paterson》,因为它更像一次生活和判断方式的校准,能把注意力从持续输入里稍微抽出来,重新放回你真正想怎样生活和做事上。
The Effective Engineer
The Effective Engineer · Edmond Lau
Chapter 1: Focus on High-Leverage Activities
A direct chapter for choosing what to work on today: it keeps attention on compounding engineering output rather than just being busy.
01
Insight
从今天的输入看,AI 原生基础设施正在从「追求速度」转向「追求实际输出」,而内容生产与学术共idious模式正形成共鸣。Hacker News 的发布堆叠呈现出三个叙事轴:Mistral Large 4 和 Decisions API 把模型能力推向专用化边缘;OpenAI 的数学仓库与EmbeddingGemma 2 则把「开源」和「实用嵌入」作为新基石,而Paramount-Skydance 的千亿美元合并则暴露出内容产业正直面算力与监管的双重稀缺。G 奖物理学家哈尔森的诺贝尔奖命中标志着科研验证进入「可解释性」时代,这一逻辑与OpenSSH 10.6 采纳 AI 安全报告的速度频发相呼应——工具链正在被 AI 代理化重构,而不再是人类的外壳。YouTube 的讨论从硬件物理(Amin Vahdat 批判 FLOPS 真实产出)到 agentic 生产力(Valon 重建抵押贷款、AI Engineer 系列关于数据库扩缩容),形成从「硬件可靠性」到「软件可验证性」的知识链条。最大的错位在于,论文的 CLIFT、MemPilot、RV-ICL 试图用自我验证和记忆调度消除 agent 的「损伤窗口」,但Dwarkesh Patel 的历史视频——Cortés 的征服策略——倒提醒我们,真正的复合决策往往藏在「跨组织协同」的灰色地带,并非可量化的循环。今天的判断是:AI 产业从「谁的模型快」到「谁的系统稳」;从「谁的 API 便宜」到「谁的流程可解释」;从「模型自我增长」回归「人类监督下的可验证增长」。眼下最值得留意的信号是,AI 正在把「数学发现」和「房贷服务」同样量化为可优化的流程,而这两种背后分别是「纯理性探索」和「监管束缚」两种截然不同现实的碰撞。换句话说,技术的递归明天不会靠更大的模型,而是靠更小的、可检验的闭环——这也是本周 Skydance 合并后,传统内容平台最难改的那道墙。 明天的导视可去找Paterson (2016)。
03
Hacker News
02
我们将内部前沿模型产生的一批新数学成果以GitHub仓库形式公开,并提供论文修订及引用规范。这是基于高等研究院独立数学与人工智能咨询小组的建议和公开推荐,旨在改进与数学界共享成果的方式并提升透明度。该做法将促使研究者在获取和引用AI生成的数学工作时采用统一的引用与验证流程,影响后续论文撰写和审稿的工作方式。
03
OpenAI发布了包含722个数学手稿及其证明作品的仓库,这些作品由内部模型生成。由于现有数学评估已饱和,OpenAI扩充了模型在开放性研究问题上的评估,部分作品基于模型先前的结果。仓库按数学学科划分372个相关手稿家族,其中大多数作品尚未获得Lean正式化,部分作品可能存在问题,将持续更新。释放的模型推理摘要显示,超过4000个问题通过固定程序获得,平均每个结果耗时三小时。
04
OpenAI 推出的 Decisions API 进入公开测试阶段,该接口可对文本和图片返回结构化答案,速度约快 10 倍。开发者可通过唯一名称标识问题答案,选择 predicate、choice 或 score 三种问题类型进行分类、路由或评分。支持以 base64 编码的图片检查产品破损、归类投诉部门或评估问题严重程度。该接口仅提供 gpt-6-luna 模型,定价按输入 token 计费。目前支持零数据保留和 HIPAA 合规,数据主权规则限制在美国和欧洲地区使用。
05
谷歌今天推出EmbeddingGemma 2,这是一款开源的轻量级多模态嵌入模型,首次支持文本、代码、图像、视频和音频统一嵌入。该模型基于Gemma 4架构,参数7.4亿,采用Apache 2.0许可证,显著提升了子1B规模模型的性能,尤其在代码任务上提升9.92分,并通过Matryoshka表示学习实现嵌入维度可变,从128到768不等,实现存储效率提升。其8K上下文窗口支持处理数分钟音频、数十张图片甚至视频帧,同时在像素11 Pro上仅需约191MB至567MB内存即可运行。
06
2026年诺贝尔物理学奖授予法兰西斯·哈尔森,表彰他作为冰箱神经观测站的关键贡献者,以及发现了源自天体的高能中微子。该奖项由哈尔森在冰箱神经观测站的工作确立了中微子天文学的里程碑,验证了冰箱探测器通过冰层作为天体微子的天然探测器这一机制成功捕获并识别了来自外部天体的高能中微子信号。这一突破为天文物理学家、粒子物理研究人员以及依赖于大型科学仪器的机构提供了全新的观测框架,改变了他们探索宇宙高能过程的方式,提升了跨学科科研合作的成本效益和风险管理能力。
07
Paramount Skydance今日完成与Warner Bros. Discovery的1110亿美元合并,新公司取名Skydance并整合两大电影工作室、Paramount+、HBO Max、CBS、CNN及其体育与内容库。因加利福尼亚州及十一州反托拉斯诉讼,法院曾认定合并可能大幅削减竞争;双方达成和解后获批,和解设定国内电影最低投资放映门槛并要求基本频道分别谈判。此举将改变内容发行方和有线电视运营商的谈判流程并提升合规成本。
08
OpenTPU 是一个由 AI 自行设计的开源 AI 加速器,支持在 FPGA 卡上运行多种大模型并与比特级仿真保持一致。它采用 LiteDRAM 控制器、四列阵列乘法单元和流引擎,使解码受 DRAM 带宽限制,且通过位流统一、固定时钟 133.33 MHz 实现全栈可读设计。这让硬件研究者能在同一仓库中从 Python 算子追踪到电线,降低理解和验证成本,同时对需要在资源受限设备上部署模型的开发者影响最大。
09
10
OpenSSH 10.6于2026-10-06发布,今年收到大量安全报告,其中许多来源于AI模型。出于安全考虑,开发团队决定加频发布以快速获取修复。该版本弃用scp的-R参数,禁用压缩编码以防侧信道攻击,并严格限制用户名字符。新风险通过sftp路径验证、GSSAPI凭证处理和压缩包大小控制得到缓解。这些变化影响需要频繁更新SSH客户端和服务器的用户,特别是依赖旧版scp参数或压缩功能的系统部署者,需要调整脚本和配置。
05
YouTube
01

Full episode: https://youtu.be/LwQQ7nBCGSs Me on twitter: https://x.com/dwarkesh_sp
02

At 100,000-accelerator scale, something fails multiple times an hour, which is why Google's Chief Technologist for AI Infrastructure Amin Vahdat thinks FLOPS is a vanity metric. The metric that matters is what he calls goodput: the useful work a workload actually delivers through real failures. Amin walks through the calculus that split the TPU line into 8i and 8t for the first time, why the TPU's core primitives haven't changed since v1, and how Google and DeepMind co-design in the same rooms, intercepting chip architectures mid-flight before tape-out. He explains why long-horizon agents are
03

a16z General Partner Angela Strange sits down with Valon’s Andrew Wang and Linda Du to unpack what it takes to rebuild the infrastructure underneath a $13 trillion mortgage market that still relies heavily on systems designed before the internet. Linda and Andrew explain why Valon chose the hardest path: becoming a regulated mortgage servicer, translating decades of federal and state regulation into software, and proving the platform on its own loans before selling it to the industry. That foundation made Valon roughly three times as efficient as traditional servicing and created the system o
04

Most teams start their evals in a spreadsheet. Here's what happens when they try to grow out of it. Hossein Niazmandi, who leads solutions engineering in the West at Braintrust, explains why measuring agent quality is much more than putting a UI on a spreadsheet. He covers the two pillars of agent quality, evals before production and observability after, and why non-deterministic LLMs make both necessary. Then he walks through the stages teams go through: spreadsheets, a custom UI, side-by-side experiments for PMs and domain experts, and finally a flywheel that turns production failures into
05

AI agents are multiplying traffic overnight. Here's how to ship fast without taking your database down with it. Ben Dicken from PlanetScale argues you no longer have to choose between moving fast and keeping things up. He covers the principles behind reliable infrastructure, isolation and redundancy, then how to scale with sharding, back pressure and decoupling, the same ideas PlanetScale uses to run databases for fast-growing AI companies like Cursor. Then he gets to agents: how a simple VSchema JSON file lets an agent design a sharding plan for Vitess, how Traffic Control sets resource budg
06
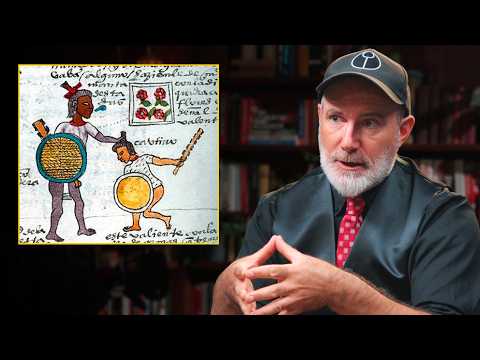
Full episode: https://youtu.be/LwQQ7nBCGSs Me on twitter: https://x.com/dwarkesh_sp
07

A small model guesses the next few tokens. The big model checks them in one pass. When is that worth it? Sheilah Kirui, developer advocate at Akamai, explains speculative decoding and how to tell whether it's worth turning on. She walks through the prefill and decode phases of inference, how a small draft model proposes tokens that the target model verifies in a single forward pass, and the memory cost of hosting a second model and its KV cache. She covers how to choose a draft model, then demos both setups side by side with vLLM on a single NVIDIA Blackwell GPU: structured output ran 1.6x fa
08
AI changed how we write code. But 70% of engineering time goes to running and fixing it. Varun Krovvidi, product marketing lead at Resolve AI, explains why AI that writes code well still struggles to run production. Code is self-documenting, modular and a single domain. Production spans code, infrastructure, telemetry and many teams, and needs one correct answer. He covers where agents crack as you scale: anchoring bias and the model treadmill, too much or too little context, coherent answers that aren't causal, missing guardrails, and no learning across investigations. Then he lays out six p
08
Papers
01
该论文解决如何仅用腕部加速度计估算睡眠心率的问题,提出基于Transformer的SeqSmoother,融合光谱描述子、Nightbeat频率锚点和物理驱动的次谐波特征来识别谐波锁定;实验表明在准确率与可用性间取得平衡,为大规模无光学心率监测提供可行的学习时序方法,对Agent/AI健康产品的传感器融合与模型鲁棒性具有参考价值。
02
TasteVal 通过 8 个开放式前沿 AI 研发任务,让被评估模型充当 Researcher 反复设计实验,固定 Coder 执行并返回结果,在算力或时长预算内衡量其实验设计与结论质量。以达到专家同等得分所需的算力为基准,算力倍率越高表示实验品味越好;最新模型 Opus 5.5 倍率达 2.3×,且自 2025 年底每 3 个月翻倍,远超之前的 14 个月周期。这表明前沿模型在自主实验上的指数级进步,对构建能自行探索和改进的 Agent 系统具有重要参考价值。
03
CLIFT 让 Agent 自行提出自然语言验证问题,用 Compositional Conformal Certifier 筛选可信信号并赋权,将验证得分加入逐步奖励;测试时复用已证题库进行轨迹选择,无需外部 giudge。在 WebArena、VisualWebArena 和 Mind2Web 上达到 SOTA,表明昂贵的 giudge 反馈可变为可复用的训练与测时信号,为低成本可扩展网页 Agent 提供直接可行方案。
04
MemPilot 通过强化学习调度多步策略,在查询无关记忆与查询特定多模态历史的即时策展之间灵活切换,共同控制证据量、指令、模型选择和视觉访问,以实现性能‑成本‑延迟的精细权衡。吧
05
06
LLM 代理用冻结 VLA 时,靠文本记忆难以利用完整演示视频——全视频慢,关键帧丢失接触细节。RV‑ICL 把演示分层构建只读工具,代理先粗览再按需载入子目标短片,免训练。一段演示就能把 LIBERO‑PRO 成功率从 92.6% 提到 96.5%,LIBERO‑Plus 从 86.7% 提到 95.8%。
07
08
ML论文的流程图需要适配不同画布比例,现有方法要么拉伸变形、要么幻觉内容或断边。本文提出由Parse、Style、Layout三阶段构成的agentic流水线,每阶段带批判器结合确定性约束和VLM视觉反馈,显式保证连通性并输出可编辑的draw.io mxGraph XML。在100张流程图五种比例的基准上,内容忠实度达68.6%,远超既有11.2‑41.4%。对需要可靠、可编辑图表生成的Agent系统尤为有益。
09
Issue Monitor
Ready now165Actionable issues
Needs review18Awaiting a fresh check
Data statusFreshUpdated 0.58h ago